Challenge
Most video lacks audio description, excluding blind and low-vision viewers from visual context that sighted audiences receive automatically.
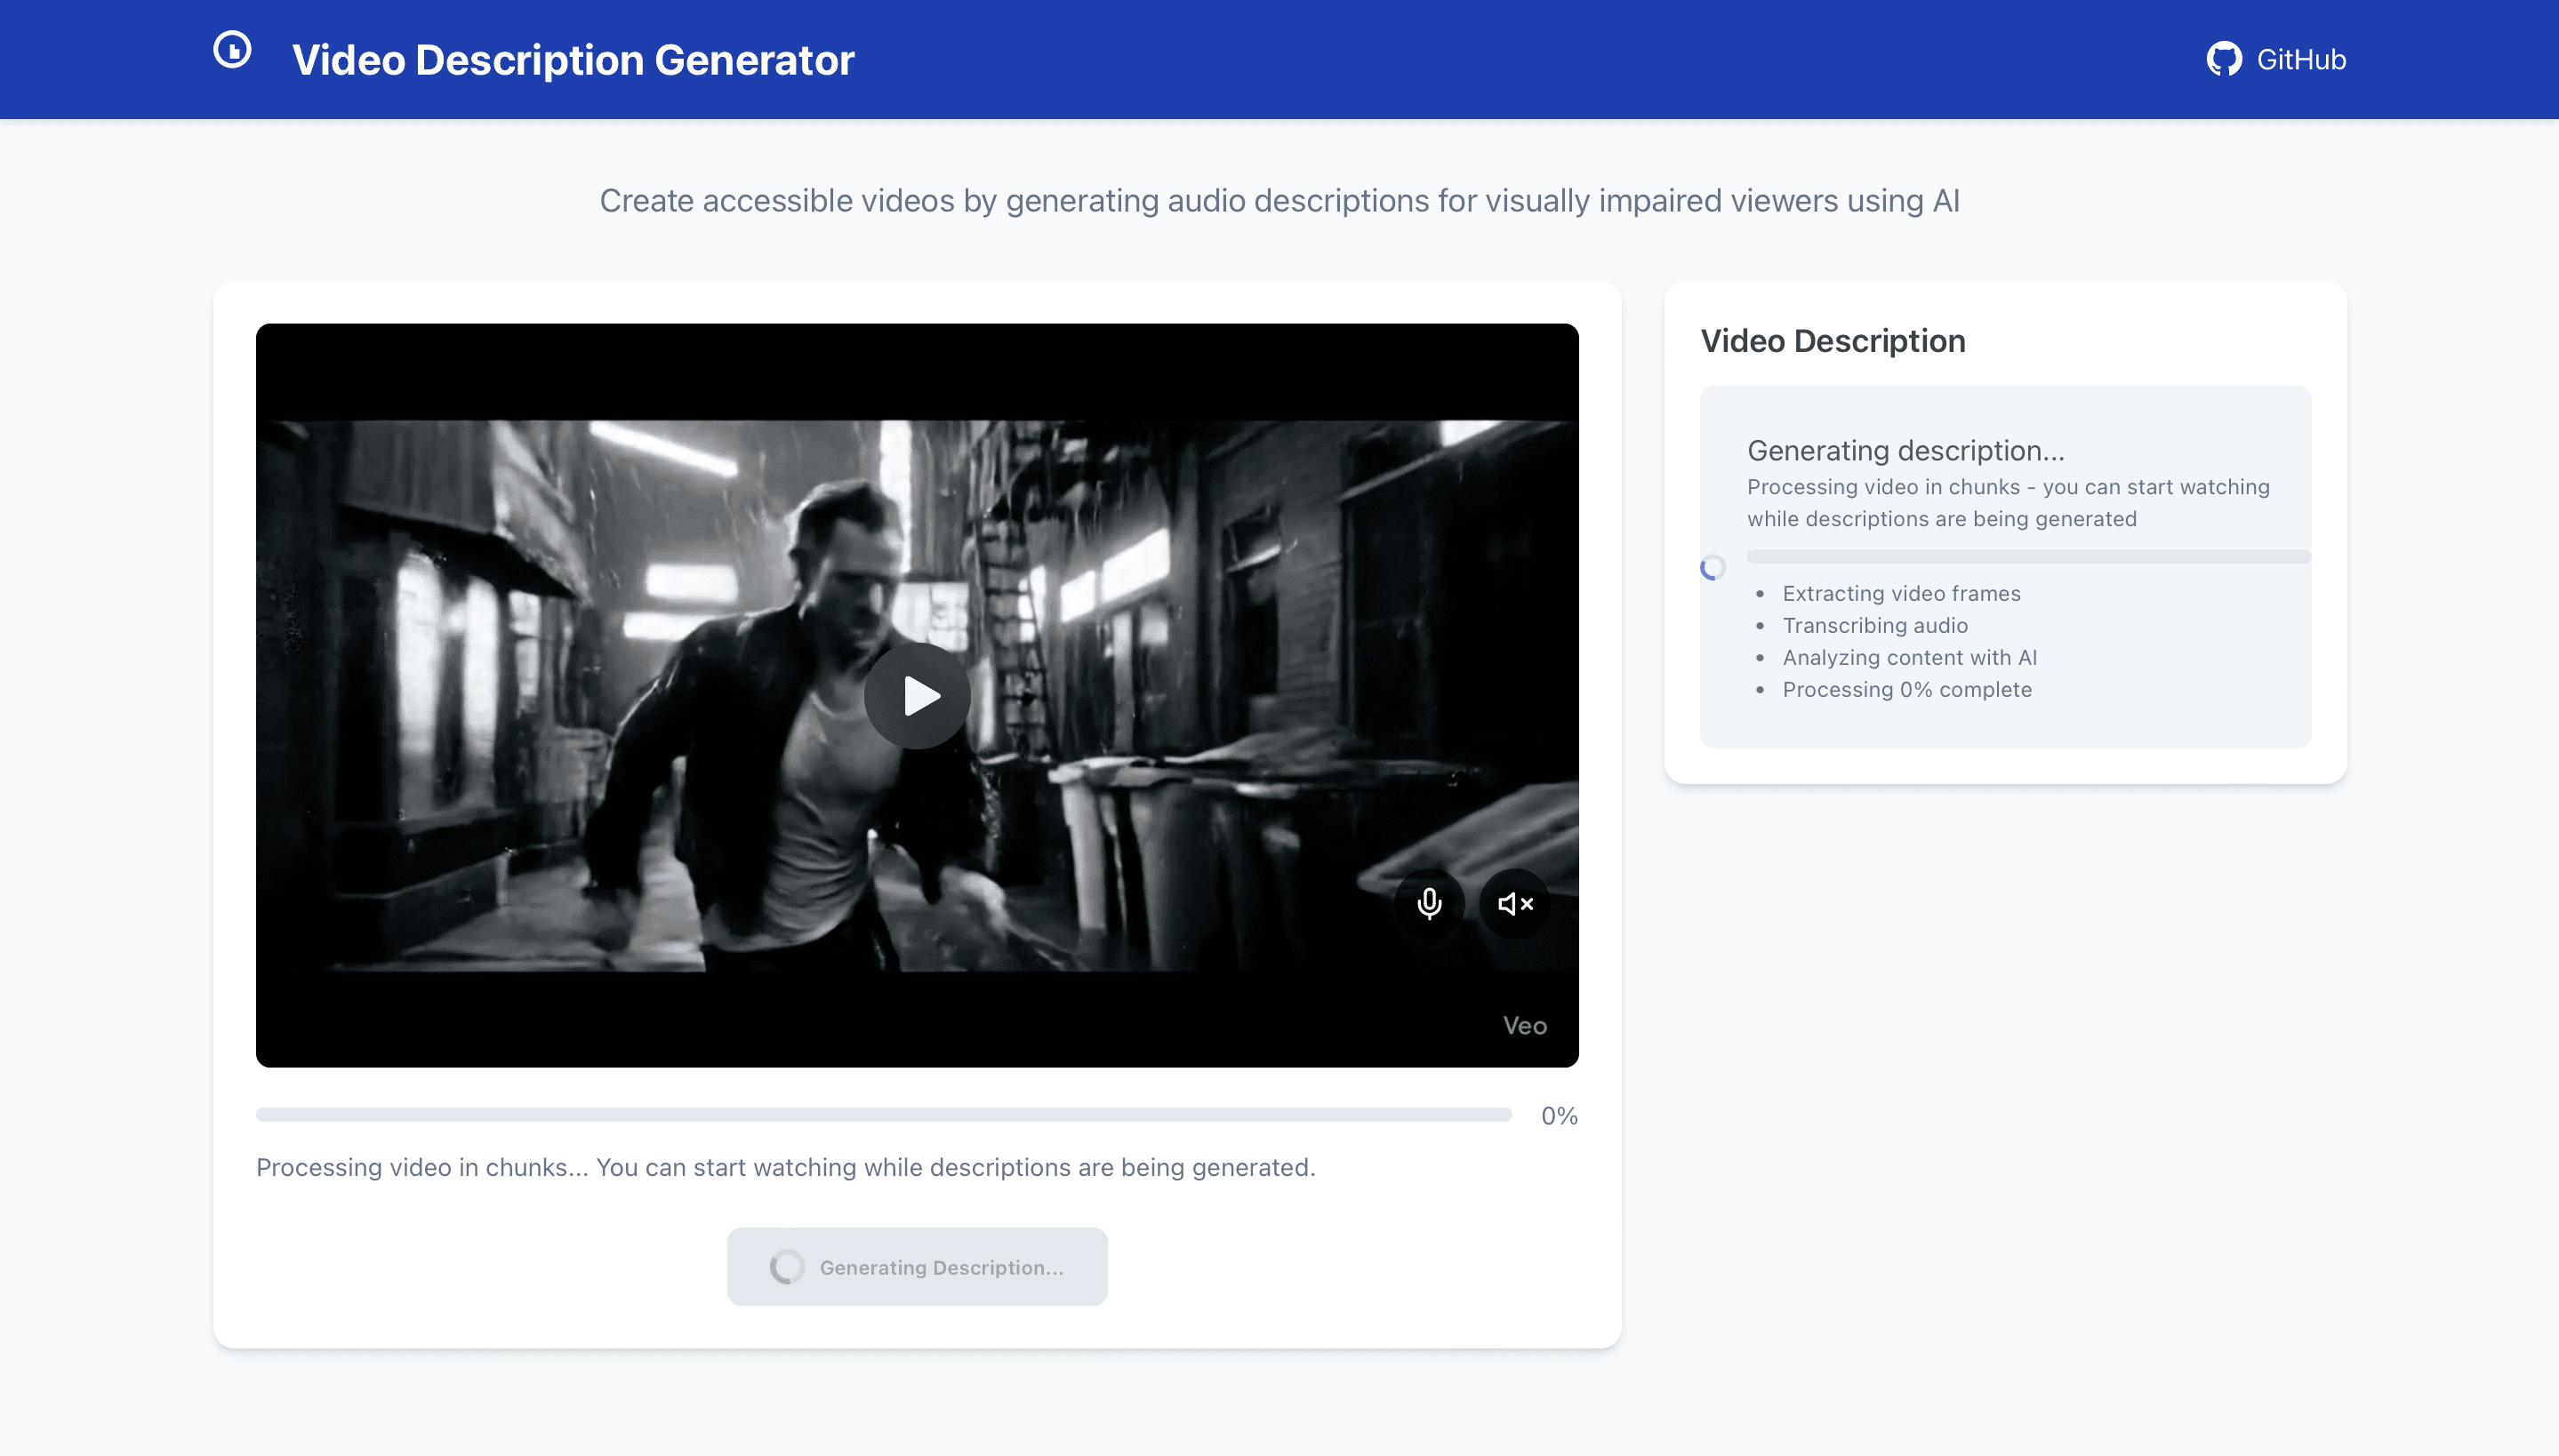
AI-Powered Accessibility for the Visually Impaired
Over 2.2 billion people worldwide have vision impairments, yet most video content lacks audio descriptions. This tool changes that using Llama 4's multimodal capabilities.
Most video lacks audio description, excluding blind and low-vision viewers from visual context that sighted audiences receive automatically.
Full-stack engineer on a hackathon prototype
Chunked video with FFmpeg, combined speech context with multimodal frame analysis, and synchronized generated narration with playback.
Produced a working Llama 4 Hackathon prototype that turns uploaded video into timed, customizable audio description.
Splits videos into 9-second segments for efficient parallel processing with FFmpeg
Analyzes video frames and generates contextually-aware, natural descriptions optimized for accessibility
Integrates OpenAI Whisper to preserve dialogue context for better descriptions
Text-to-speech narration plays in sync with video, with customizable voice settings
Auto-detects Chinese, Japanese, Korean, Arabic, Spanish, French, and more
Choose voice, adjust speech rate and pitch to preference
Accessibility work benefits from treating timing, dialogue, and user control as first-class product constraints rather than post-processing details.
Full-stack engineer on a hackathon prototype